I’ve written before about the tools I’ve built to manage the workload and gather statistics on activity of students in my Data Structures and Algorithms course.
To recap, the tool is needed due to large number of students in the course (and others, going on simultaneously), while the teaching resources are quite petite, to put it mildly. Last year the total enrolment count was ~350, this Fall it is ~230. Repository count this year is (currently) ~200.
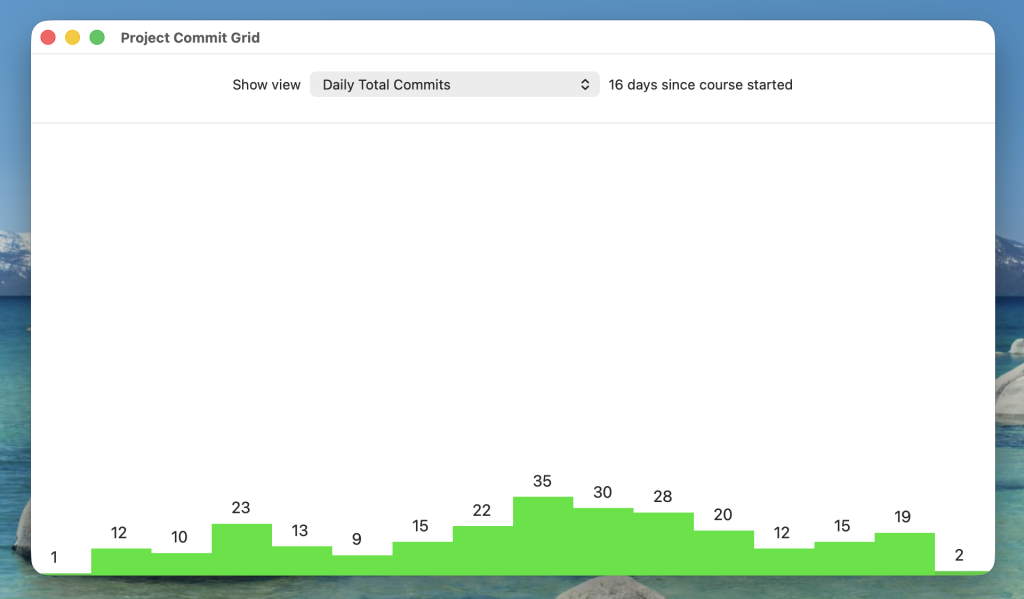
What kind of activity statistics? Like the total number of daily commits from the start of the course, done by students:
Bar chart of count of git commits per day in a programming course with ca. 200 students.
Someone made a git commit on the first day of the course, and the most active day so far was the ninth day with 35 commits in total.
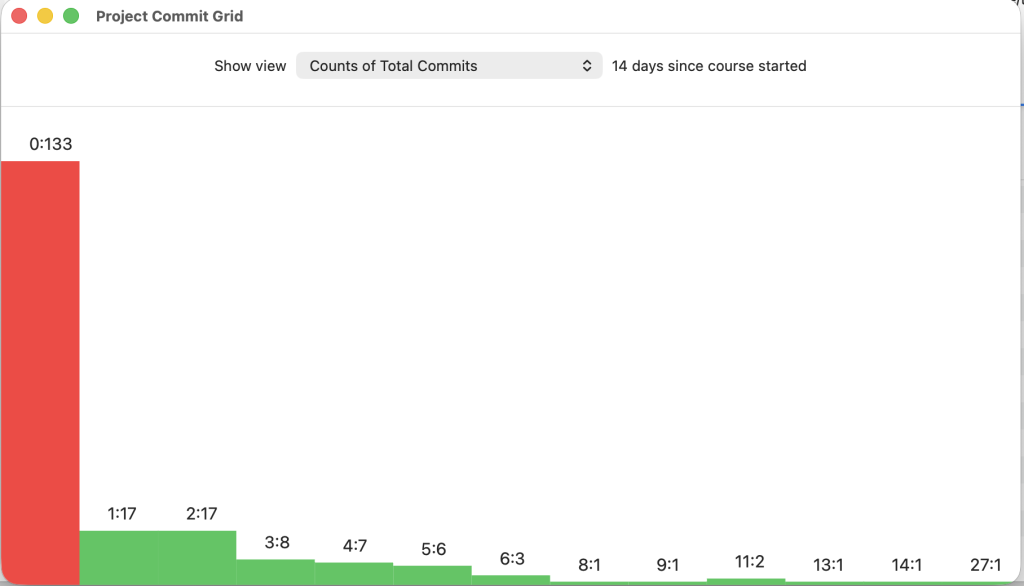
Or the repositories having a specific count of commits currently:
Bar chart displaying the count of student git remote repositories having a specific number of commits so far. Zero commits in remote repository accessible to teachers does not indicate zero work. Student may have commits in their local repository or uncommitted work not yet in git.
The graph above shows that 133 repositories have zero commits at the time this analysis was done, 17 repositories have one commit, etc. The most active student has done 27 commits already.
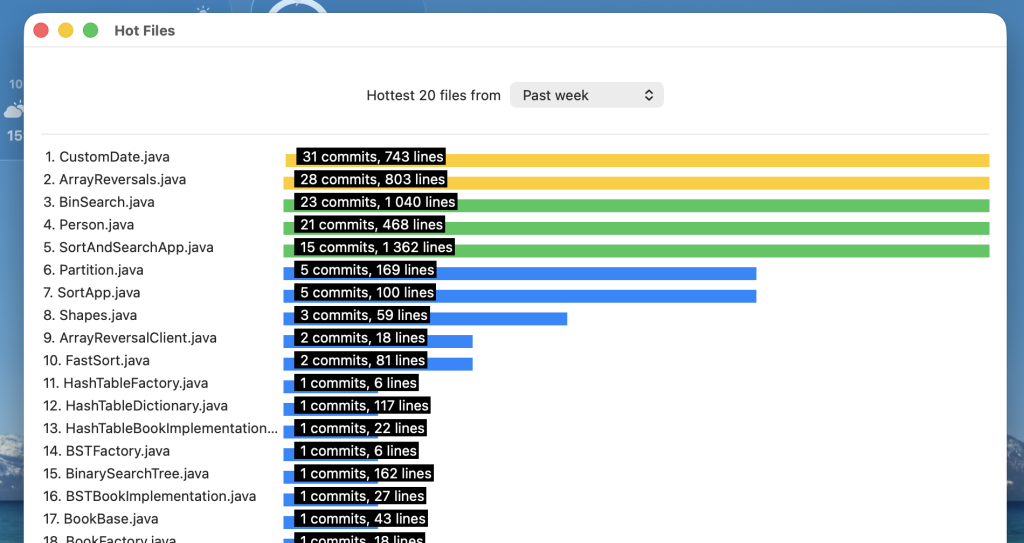
This data graph shows what have the students been working on during the last seven days:
A chart displaying the most actively edited files based on commit counts and changed lines in all student repositories.
Which looks quite what is expected, since the first five Java files are supposed to be worked upon in the first three course programming tasks in the schedule this and previous course weeks.
These are all based on my Swift/SwiftUI app analysing the data from git and git logs, either stored in my app’s database or parsing from the output of git log command, as the analysis is executed and the graphs are generated.
But what about the activities related to the lectures? Assumption is, obviously, that the students first go through the lectures and lecture demonstrations and only then dwell into the associated programming tasks. An assumption that does not unfortunately always hold, but still…
We use Moodle as the learning environment. While Moodle has extensive and detailed tools to analyse and observe student activities, getting a quick overview from those tools can be a bit cumbersome.
For example, when you view the activity log of a link to a lecture video in Moodle, you can see who and when has accessed that link. But if the same student clicks the activity’s link several times, there are several rows in the activity log for the same student. Also, that log does not quickly tell me the total count of students who have accessed the lecture video at least once. I’d have to do the counting myself manually.
I’ve split the lecture videos to a manageable lengths (from the viewing perspective) which means there are 25 video links currently of the actual lecture content. In addition to that, there are some demonstration videos. Clicking through the Moodle analytics on all of these and counting by hand how many students have accessed the videos is therefore not something I’d do e.g. weekly. Too much manual, tedious and error prone work.
This is not a one time chore, but a thing to do many, many times during the course. Preferably weekly from September to December. Then the teachers would be on the map about the students advancing in the course, week by week.
Using the analytics data, we at least theoretically could be able to observe something relevant happening (or something not happening what was supposed to happen!) that could indicate problems somewhere in the course implementation. Maybe the data could also be used to improve the course for the next year, pinpointing places where the planned schedule and actual realities do not match and it is the course schedule that should be adjusted.
Fortunately, Moodle offers a download link for each activity log report. I can choose the format of the downloaded file, one of which is JSON. So, I implemented (no LLMs used, as usual!) a command line tool using Swift, which
reads the downloaded Moodle JSON analytics files from a specified directory,
reads the activity name from the JSON file contents,
counts the unique student names in that file, and then
updates a tab separated values (tsv) file where the statistics (no student data is stored) of each Moodle activity are stored, per analysis date, and
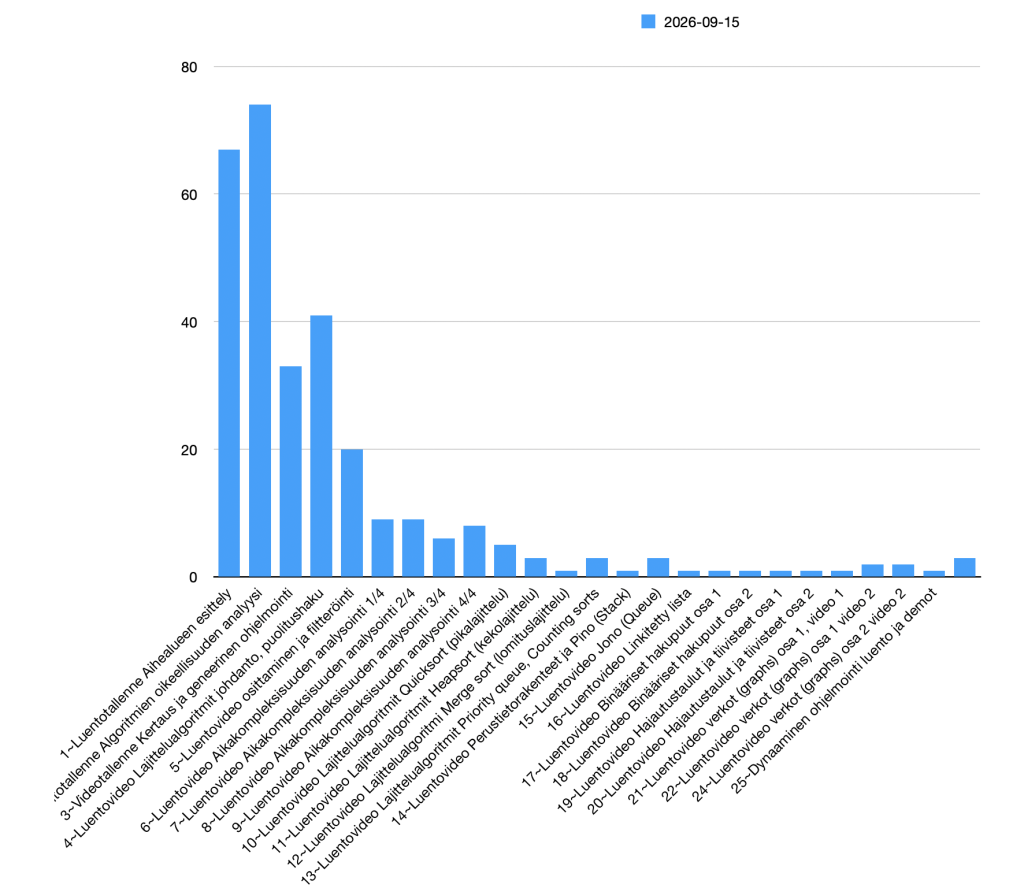
the tsv file can be opened in a spreadsheet app and data can be visualised as a graph:
A bar chart displaying the Moodle activity access counts of course lecture videos, gathered from Moodle activity logs. The chart tells me that many students have not yet started to watch the lecture videos but are falling a bit behind of the schedule. Not yet alarmingly so, but let’s see how it goes. It is always possible that some watch videos together, only one student accessing the activity while many are actually watching. A very good thing in itself, but may influence the statistics.
The relevant part of the JSON file handling is:
func processJSONFile(_ file: String) throws -> (num: Int, act: String)? {
  let fileContents = try String(contentsOfFile: file, encoding: .utf8)
  if let jsonData = fileContents.data(using: .utf8) {
    var uniqueUserNames: Set<String> = []
    var target = "" // The Moodle activity name

    let jsonDecoder = JSONDecoder()
    let items = try jsonDecoder.decode([[MoodleStatisticsItem]].self, from: jsonData).flatMap( { $0 } )

    for item in items {
      // Ignore the listed teachers who clicked the activity link.
      if !ignoreNames.contains(item.kokoNimi) {
        uniqueUserNames.insert(item.kokoNimi)
      }
      if target.isEmpty {
          target = item.tapahtumanKonteksti.replacingOccurrences(of: "Verkko-osoite: ", with: "")
      }
    }
// ...
What is actually collected and later saved to the tsv file from this, is the uniqueUserNames.count, telling the number of individuals (excluding teachers) who have accessed the Moodle activity at the time the tool was executed, as well as the name of the Moodle activity from within the JSON file, in target.
Now, instead of spending tens of minutes or even hours, clicking and manually counting things from the Moodle activity logs, I’ll spend maybe 5 minutesmax to download the JSON log filesactually only like seconds, since I just changed the tool to handle just one JSON file containing all activities of the course, and one second to execute the tool and open the resulting file in the spreadsheet app. Huge time savings!
All this done, by the way, when I was (still am) sick from a flu and can’t go teach in the classroom. Implementation took less than a workday. No employer’s time wasted doing this, just my sick day, but saving employer paid work time later! [Do not work when sick. I did because I like programming and didn’t consider this work, actually, but an interesting problem to solve.]
When I used the tool first time, the resulting graph above shows the activity stats of course lecture videos for that date, Sept 15th. I plan to launch the tool once a week, so it is then possible to see the difference to last weeks’ viewing stats. The next time launched, a new entry is added to tsv file for that date stats.
Knowing the recommended course schedule, I can then use the tool to see how the students actually advance through the course lectures. This should also give more insight into the git based programming task analytics.
If, for example, the graph above shows that students are advancing into the Stack data structure lectures a week after the planned schedule, teachers could expect that the students are actively starting the related coding tasks that week or the next one. Then we could be better prepared to handle the inevitable issues and questions about stacks at that time. Or we could anticipate that when the deadline comes, a certain number of student are behind the schedule and may need additional support to actually pass the deadline without issues. Hopefully.
The only manual thing left to do is to actually download those 25 Moodle activity JSON log files. I bet I could somehow record a script that does that clicking and selecting type of downloads in the browser automatically too… 🤔
The Fall semester was again another hectic run through the courses, without much breaks. Three courses with two full time and two part time teachers helping, having nearly 900 students. No wonder…
Regarding my latest posts and this situation, I did manage to solve Advent of Code up to part 1 of day 10. Part 2 is still WIP, and I do have some ideas about that. But don’t know if and when I return to that, if ever.
Much of the teaching work at Fall was conducted not in prepared teaching sessions, since for some reason, many students nowadays do not seem to want or need to come to lectures or exercise sessions. Though we teachers sat though them all! Well we did cancel some sessions at the very end since nobody was coming, but anyways.
We even had to arrange three classroom sessions for the Fall, since last year (2024, fully online teaching) students demanded at least some face-to-face teaching for 1st year students. They even went to the Dean of the Faculty to make sure this happens.
Almost nobody came. Less than 20 students (out of ~900) from those three courses went to the classroom sessions, if I remember correctly. Not very effective use of teaching resources, IMO. Hopefully those who came found them valuable!
Well, we have video lectures and other support (Web based FAQ tool in Moodle, email), and major part of the teaching happens via these. Maybe we should be happy that the course materials and the support we do provide is enough for those students that decide to continue in the course. Some enrolled to my DSA (Data Structures and Algorithms) course do not, since they never provide the URL to their project repository or quit after first 1-2 programming assignments.
In the FAQ tool in DSA, I published 47 new FAQs in addition to the 33 old FAQs from the previous course implementations. Many of the solutions in the FAQs could have been avoided if carefully reading the course materials, watching the lectures and following the instructions in the programming assignments. Anyways, maybe the FAQs also contained explanations and points that somehow provided additional help to the students.
I also moved DSA course exams to controlled exam environment. Because of AI slop and cheating is on the rise. Some small hiccups there I need to fix, but seems to work overall.
To make preparing exams a bit more efficient, I implemented several console based tools (in Swift) that generate random Exam questions, also with image attachments. I have tools to generate questions about binary search algorithms, hash table and hashing using linear probing, as well as tools that generate questions testing if students understand how nodes are added to Binary Search Trees. And how to conduct breadth-first-search and depth-first-search to graphs.
Whenever I like, I can then generate new questions, to make sure every student has their own unique set of questions for their exams.
Today I refactored a part of my code analysis tool. The tool and the refactored feature helps me to check if the 300-something students in DSA have used solutions in their code that must be avoided or are forbidden (e.g. calling Java hashCode() when they should have implemented their own, or calculating the hash from wrong things). Or to make sure they have used elements that must or should be used (e.g. calling a function from itself, when recursive code is required). Something teachers could do manually, but since we do not have those teachers in the numbers required for manual work, automation comes to help.
The analysis code used Antrl to parse the students’ Java code to search for things that are not OK and must be OK. While it worked nicely in my Swift app, Antlr was very slow in debug builds. It was a bit faster when the app was build in release configuration, but still slow enough to be annoying.
So instead, the new implementation just runs a Java console app in a Subprocess, using the Swift Subprocess library. I implemented the same code analysis tool as a Java console app and gave that to the students, using com.github.javaparser for the source code parsing.
Using the tool, students can check, before deadlines‚ that they have not done anything stupid. Avoiding to get failed grade after the last deadline, as they can use the tool to check and fix any obvious wrong solutions during the course. Preferably before deadlines, as they will get sanctions on using solutions that are not accepted.
I needed to modify the Java app a bit so that the Swift app I use can launch it and use the output to record results to my Swift app’s database:
modified the command line parameters to include output format, either “text” or “json”. Default is text, so students can see more understandable output from the tool. Given the “json” parameter from my Swift app to the Java app explicitly, produces JSON formatted output my Swift tool reads from Subprocess’ stdout.
Make sure the Java app output to stdout contain only the JSON, containing the issues found in the code, when “json” format was selected. So the Swift app can then rely on the received output to be valid JSON.
Fix some issues in the code analysis output at the same time, that lead to invalid JSON. Like having unescaped quotes in the analysis output, or line endings like \r which messed the output not just in JSON but also in text format.
This change makes also sure that the Java app the students use is behaves exactly as my tool. No surprises in what the tool reports and does not report to students, compared to the results the teacher sees.
Java app executed in the subprocess executes definitely faster than the Antlr implementation in Swift. Additionally, I managed to strip down tens of lines of code, the Antlr generated Java parser removed, plus the dependency to the Antlr library from the Swift tool project is now gone.
Advent of Code (AoC) for this year started yesterday. I’ve been too busy with work to write here how my puzzle solving has been going. Or anything else, for that matter. Probably will be for the rest of this year.
Why busy? I’ve been moving Data structures and algorithms course exams from Moodle to Exam. Exam is a controlled environment as Moodle was not (at all). There is a tool to import Moodle exam questions to Exam but that is so limited that I decided to hand write new exam questions for this year.
This has taken time, also learning how the Exam works since I have never used it before. Also I’ve been preparing new demonstrations and visualizations for the course to aid learning. There’s still one visualization demonstration to do, namely how the Dijkstra’s shortest path algorithm works. If I do not find the time for that, I just have to search for existing demonstrations from the internet. Would like to use the familiar graph examples from the lectures and other demo materials though.
Anyhows, I have solved both Day 1 and Day 2 puzzles in AoC, using Swift as last year. If you wish to see how the actual puzzles look like, just head on to the AoC website.
Yesterday’s part 2 was a bit difficult, mainly due to some basic mistakes I made in the beginning, and not starting from scratch when I saw the mistakes I had “fixed” with unnecessarily complex code. Sauna break in the evening helped, teaching and other work in between less so 😅. And starting from scratch was a good idea.
Day 1 implementations were fast, part 1 took 0.000684708 seconds to execute, part 2 took 0.000698 seconds (on MacBook Pro M2, Swift implementation, release build, obviously). Lines of code I needed for the part 1 solution is 18, for part 2 line count is 32.
Day 2 implementation’s Part 1 (17 lines of code) took 0.150482667 seconds to execute, while part 2 (27 lines of code) took 0.437480584 seconds. Here I was using Swift’s .split, .map, stride (a for loop kind of a thing) and chunks(ofCount:) from Swift Algorithms package. Much more straightforward (for me) than yesterday’s part 2.
Now to lunch, then to prepare for a MSc thesis supervision session, then to teach (remotely, as usual) for the rest of the afternoon.
Years ago I developed a watchOS app Slippery Weather (Liukkaat kadut in Finnish) displaying pedestrian slippery weather alerts to users. I sold it at the App Store, and later lowered the price to zero, offering it as a free app.
Apple Watch displaying an alert in a Slippery Weather app widget about slippery weather notification given two hours ago in the city of Oulu.
However, I didn’t have time to maintain it, so I took it off the App Store recently. That was a good decision, since I’ve now learned that the service providing the alerts API has ceased to operate.
The service got the slippery weather condition alerts from the participating cities (road maintenance folks) in Finland. It seems that the cities have switched to using Finnish Meteorological Institute (FMI) weather model based alerts instead.
I do have a prototype watchOS app using Apple Weather service local weather data. The prototype attempts to predict slippery weather for the next 12-24 hours, based on recent and forecasted temperature, precipitation and humidity. But haven’t had time to work on that either. Doesn’t work so reliably that I would want to publish the app.
Learned a lot while developing the app though. Everything lasts for their allotted time, nothing is permanent.
I read an interesting question about Monitor structure in Swift Forums. The question was how the way it is implemented in Java using synchronized methods compares to Swift concurrency and actors.
Well since this was interesting and I wanted to learn more, there was simply no other option than to pick up the code editors and start coding…
In an earlier post, I mentioned an issue that the deadline list rows were not updated properly while looking at the deadline coming and going. And that the solution was to do this:
@Observable
class Deadline: Codable {
// ...
   var viewUpdateNeeded: Bool = false
//...
   var isReached: Bool {
      viewUpdateNeeded = date <= Date.now
      return viewUpdateNeeded
   }
That is, to update an observed value viewUpdateNeeded to generate a change event to the @Observable so that SwiftUI view would get updated properly.
I do not know if the code above always had an issue I just didn’t see. Or did an update to Xcode and Swift/SwiftUI libraries change something. But anyways, what I did notice afterwards was this:
Start the app.
Hide the left side course list view (when the ContentView showed ContentUnavailableView since no course was selected).
In this use case scenario, everything works OK. But if I did this:
Start the app.
Select a course from the course list on the left (ContentView displaying the deadlines of the currently selected course).
Hide the left side course list view.
Then the app would get stuck, freeze totally, at step 3 (not at step 2). Why this happened is that the list row view got updated repeatedly, so that the app used 100% of the CPU.
I saw this happening when testing the app in Instruments and looking at which operation was taking the most of the execution time. Then I placed a breakpoint into that piece of code and repeated the two usage scenarios. That showed me what was happening – app was not frozen but too busy updating the list rows that it became unusable.
The reason was the line viewUpdateNeeded = date <= Date.now “changed” the value of viewUpdateNeeded from false to false repeatedly and SwiftUI then repeatedly rebuild the view. While I was in the impression that this was not supposed to be a change. Only if the value would actually change from false to true or true to false would be a change that would cause view rebuilding.
Either I had misunderstood how SwiftUI works, and my original solution did not work at all, but I just didn’t see that happening until I dit the second use case scenario with the app. Or something changed in how SwiftUI works, and then this became a bug.
Whichever, I do not know. I have no idea why this happened only when hiding the list of courses, since the course deadlines were already visible at step 2 in the second scenario.
Anyways, this change got rid of the bug:
@Observable
class Deadline: Codable {
//...
   var viewUpdateNeeded: Bool = false
//...
   var isReached: Bool {
      if date <= Date.now && !viewUpdateNeeded {
         viewUpdateNeeded = true
      }
      return viewUpdateNeeded
   }
That is, change the value of viewUpdateNeeded only when the condition becomes true.
UI testing is important, folks. Unfortunately I did not implement any automated UI testing for this app, so finding the bug was just by a chance. Regression testing is also important, to check if the app still works after updating the tools, frameworks and libraries used by the app, to catch any changes and possible issues caused by the changes there.
I think it was when having my morning coffee and loitering the internets, I saw somewhere this discussion:
“Here something that woud be really useful for PG development going forward: A count of the occurrence of unicode code points used in PG texts.”
PG refers to Project Gutenberg, where they publish out-of-copyright books for anyone to read for free, in various languages and formats. Highly recommended, btw, if you didn’t know about them before!
Since I’ve done something like this before, just with words, not Unicode code points, I thought I’d give this a try. Especially when using several books from Project Gutenberg as test material in my Data Structures and Algorithms course. Gotta give back, as you know.
I only know just the basics of Unicode, like: it’s hard and complex, full of rabbit holes to fall into if you are ignorant or assume too much. On the other hand, Swift should be one of the best languages to handle Unicode correctly with the String and Character class.
The tool I made (ducking other responsibilities, again!) is available in GitHub. I commented about the tool in the PG issue discussion, as well as my noobness in correct Unicode processing. Hopefully this and/or the other implementations/data offered to them is usable for the purpose. If you know Unicode better than me, please tell me if there’s something to improve in the tool.
A useful site found while doing this is Unicode Explorer. Worth a bookmark.
As what comes to PG folks’ discussion on “…A recent issue #271 notes that the 2em dash is often used but missing in many typefaces.” — my implementation found that the 2em dash (“⸺”, Unicode symbol with codepoint U+2E3A) occurs in the provided book dataset 8 414 times.
Going to mark the hours of this little job in the category of “contributing to the culture & society” in my university work plan 🙌🏼✌🏼(the hands are codepoints U+1F64C U+1F3FC and U+270C U+1F3FC, the symbol itself plus the Fitzpatrick skin type / color…).
To end this post, here’s some technical details on the implementation. Processing the books is done using a Swift task group, concurrently (some details removed from the actual code):
try await withThrowingTaskGroup(of: [Character: Int].self) { group in

 if let enumerator = fileManager.enumerator(atPath: books) {
  while let file = enumerator.nextObject() as? String {
   if file.hasSuffix(".txt") {
     fileCount += 1
     // Add a task to task group to handle one file
     group.addTask { () -> [Character: Int] in
       var taskCodePoints: [Character: Int] = [:]
       let fullPath = booksDirectory + file
       let fileContents = try String(contentsOf: URL(fileURLWithPath: fullPath), encoding: .utf8)
// ...taskCodePoints contains the result of one file
            return taskCodePoints
         }
      }
   }

   // Combine the results from various concurrent tasks totaling the result
   // from all files:
   for try await partial in group {
      for (key, value) in partial {
         codePointsUsage[key, default: 0] += value
      }
   }
}
The data structure [Character: Int] is a Swift dictionary of key-value pairs. Key (Character) is the unique characters read from the files, and value (Int) is the occurrence count of each character — how many times it was occurring in the books.
Each subtask collects a count of character occurrences from one book, and then those are merged together in the for try await partial in group structure, as the subtasks finish.
Watching from the Mac Activity Monitor, I saw that the app used to have nine threads, processing the books in parallel on my Uni work laptop (MacBook Pro M2). For some reason, my own older MacBook Mini M1 was usually much faster in processing than the M2 MacBook.
Apparently I like coding with the Course Deadline Counter app, now renamed to Course Deadlines app. I really, really should stop doing this, and focus on something else more acute and important — that’s why the call for help. I need to be stopped!
[I am aware of this being my own responsibility, thank you so much, so plz do not send halp.]
As a new feature, the app now has a timeline View:
Where you can view the deadlines of courses currently ongoing. The view does not show courses that haven’t yet begun or courses where the last deadline already passed.
For a student user, viewing all ongoing courses is more important, to be able to view the deadlines of the courses she is currently taking and how they relate between all the work she needs to do.
For a teacher, it is more relevant to show the deadlines to students in a single course. So limiting the view to just that one course is more important, using the drop down list at the top of the view.
Considering the needs and usage patterns of different groups of users is taught in our GUI design and programming course (Programming 4). So obviously I have to be able to do this stuff myself. Consider that done, at least in this case.
For drawing the course and course deadlines, I used the SwiftUI Canvas and for the gradient background, MeshGradient. I should still test the colors with both light and dark modes and find a usable combination of colors and an overlay to mute the colors when and if they are in disagreement with the text.
Drawing on the canvas is just simple drawing operations using the GraphicsContext, plotting the text and symbols on calculated coordinates. For example, if there are no ongoing courses, the code draws only the text “No courses to show”, in the middle of the view:
Canvas { context, size in

   var origin = CGPoint(x: 0, y: 0)
   let text = Text("No courses to show").font(.title).bold()
   let resolved = context.resolve(text)

   if coursesToPlot.isEmpty {
      // Draw info that there is no ongoing courses to show
      var textSize = size
      textSize = resolved.measure(in: size)
      origin.x = size.width / 2 - textSize.width / 2
      origin.y = size.height / 2 - textSize.height / 2
      let rect = CGRect(origin: origin, size: textSize)
      context.draw(resolved, in: rect)
   } else {
// ...
With the Picker, choosing to show all courses or just one, I searched for different solutions from the internet, and chose this one:
So there is the “show all” option where the course selection is then set to nil. Otherwise, the selection is the selected course. This enables “no selection” or as it is handled in this case, “all are selected”.
I think I got to use the Swift if expression (different from the usual if conditional statement) here the first time, handling the above picker selection:
let coursesToPlot = if let selectedCourse {
   [selectedCourse]
} else {
   deadlines.ongoing.sorted(by: { $0.startDate < $1.startDate } )
}
In plain English: if the selectedCourse is not null, let the coursesToPlot be an array containing only the selectedCourse. Otherwise, get all the ongoing courses from the deadlines, sorted by starting date ascending, and let the coursesToPlot be those courses.
The next time I touch this app should really be in the end of August or beginning of September, when I decide on the deadlines of the courses I am responsible for.
In the other news, I was today awarded as the Distinguished Teacher of the Year (again) by the study program student guild Blanko. Thank you! I am so humbled to receive this appreciation for the work we are doing here.
Three days ago I wrote about the Course deadlines app:
I list some future improvement ideas in the GitHub readme, but don’t actually know if I am going to implement those. The app already fulfills the intended purpose, so anything else would be just something fun to implement, if I have the time or motivation to do them.
And now, after three days, I’ve implemented:
alerts; the app now alerts about the incoming deadline when it becomes “hot” using UserNotifications framework,
pick a symbol; the app now has preselected SF Symbols to choose from when adding or editing a deadline,
icon; app now has an icon,
app checks that the course name and deadline goal are not empty,
app checks that the course name is unique when creating a new course, and
several GUI enhancements and bug fixes.
As if it looks like I am using the app to avoid some other (not so fun) responsibilities and instead spend time on this hobby project… Though this is related to teaching work, really!! Valid work done here!!
One of the important bug fixes was related to setting the date and time for a deadline. I use the SwiftUI DatePicker for this, specifying that I want to select both date and time, using displayedComponents: [.date, .hourAndMinute] for the picker.
I was falsely assuming that the Date object would then contain the exact date/time selected by the user. Like if the user selects, using the picker, 2025-05-15 12.00, the date object then would have that exact time. Well, it does contain that date and that time, but since the user is not selecting seconds, the date object may then contain something in the seconds, like 2025-05-15 12.00.46, for example. Not good, since now the communicated deadline is actually later than the intended deadline.
I noticed this issue when I was testing the alerts feature and saw that the actual date and time shown in the alert was not the one specified in the deadline, by the seconds.
What I needed to do was to take the user selected Date object, then set the seconds part of the date to zero and then use that modified datetime as the actual deadline date:
extension Date {
   func secondsRoundedToZero() -> Date {
      var components = Calendar.current.dateComponents([.year, .month, .day, .hour, .minute], from: self)
      components.second = 0
      return Calendar.current.date(from: components)!
   }
}
Oooh, those pesky dates and times can really be hard sometimes…
There was another interesting issue with SwiftUI and the deadline formatting. The app shows a hot deadline colored red, as in the example in this image:
A deadline coming after one day and five hours.
And when the deadline has passed, it should be grayed out, like this:
A deadline gone nine days and 17 hours ago.
This worked, when you open the app and view the deadlines just loaded from files. But if you open the app and actually watch a deadline date/time coming and passing, the formatting did not change. WTF?!
As you can see, the time is shown as relative to current time. That worked fine, but as the deadline came and passed, the relative time changed to past but coloring did not.
That was because SwiftUI updates the view when the @Observable object (Deadline in this case) changes. But the deadline object actually did not change at all. No member variables changed values when the deadline date/time comes and goes. The deadline’s date and time was still the same, of course.
The way the time is shown as relative time by SwiftUI Text element, gave me an illusion that something keeps changing. Since the view shows a countdown including seconds (when the deadline is very near) when .relative style is used:
Text(deadline.date, style: .relative)
From the SwiftUI viewpoint, nothing changed so view update was not needed, thus the formatting did not change.
I solved this by adding a property viewUpdateNeeded to the Deadline. That property was then updated in the isReached computed property…:
@Observable
class Deadline: Codable {
// ...
   var viewUpdateNeeded: Bool = false
//...
   var isReached: Bool {
      viewUpdateNeeded = date <= Date.now
      return viewUpdateNeeded
   }
…used by the list item row view:
HStack {
   if deadline.isReached {
      // Show deadline as passed
      Text("Deadline passed")
         .padding(.trailing, 0)
      // ...
   } else {
      // Show deadline as forthcoming
      Text(deadline.date, style: .relative)
         .padding(.trailing, 0)
      Text("until deadline")
         .padding(.leading, 0)
// ...
}
.foregroundStyle(deadlineColor)
Where the last line, .foregroundStyle(deadlineColor determines the color used (where the deadlineColor is a property in the deadline row view):
var deadlineColor: Color {
   if deadline.isReached {
      return .gray
   } else if deadline.isHot {
      return .red
   } else if deadline.isDealBreaker {
      return .orange
   } else {
      return .accentColor
   }
}
OK, so the initial value of Deadline‘s viewUpdateNeeded is false. When the view accesses the isReached property to decide the formatting, and the deadline is still in the future, the value of viewUpdateNeeded is set.
As the value was originally false, and the new value is still false (since deadline date is not less than current date; in the past), so from the viewpoint of SwiftUI, nothing changed and view does not need updating.
When the deadline finally comes and goes, the value of viewUpdateNeeded now changes from false to true (deadline date is smaller than or equal to current datetime) and then SwiftUI sees a change in the state of the deadline object, and now the view is updated and the also formatting changes.
Of course I knew this already. Maybe I just got confused seeing the UI changing and thought, when looking at the deadline closing: “nice, things change and view is updated” and then was astonished why the formatting did not change. After a while, looking and thinking, I realized what I already knew and then added that member variable to handle the issue.
Often we stumble with the basics, and that is OK. I remember reading from somewhere that experienced programmers actually do more mistakes than novices since they typically work faster. The difference is that with experience, you are able to spot your mistakes much earlier and are usually able to solve the issues much faster. So go gather some more experience!
In the post last week I mentioned that I’ve added new features to the tool I use in Data Structures and Algorithms course to supervise, support, test and grade the student programming course work. I’ll describe here the new features and provide some (hopefully) interesting implementation details about those.
Background about the course that helps in understand the role of this tool:
students each have their own github or gitlab repository to where they fork the initial status of their course work from the teacher repository,
repository contains the task instructions, skeleton code to implement, unit tests code and other supporting code given ready for students,
repository tests enable testing the student’s implementation of the data structures and algorithms that are required to implement in the course,
teachers have access to the student repositories to assist students with any issues, and finally to grade the work.
Before going into details, a comment about the motivation for this tool to exist in the first place: The course the tool is used in, has 300+ enrolled students and only two full time teachers (sometimes we do have 1-2 assistants with small number of hours, like 50 hrs in total for the whole Autumn), simultaneously teaching 2-3 other 200-300 student courses. That totals around 900+ active students taught simultaneously, so providing individual support and attention to all is practically impossible, at least if no automation (and other support tools) is taken into use.
So the critical thing in managing all this work is, that we do need automated tools to:
keep track of how the students are progressing in the course and help those who desperately need it, and after the last deadline,
to evaluate and grade the students’ programming submissions as fast as possible.
The grading should be done in three weeks after the last deadline, so it cannot be done in time manually. The aim is to use this tool during the course, trying to catch those students that are not doing OK, and then try to contact and help them in getting their coursework going and spotting any possible mistakes in their work so that they can correct their mistakes before the final deadline.
Students next Fall will receive the same unit tests and the same code analysis tools (in Java unit tests) they can also themselves use. However, this is not enough, especially if the students do not contact the teachers about their issues soon enough or at all. A problem that is too common, unfortunately.
The new features added to the teachers’ tool during this Winter and Spring are:
Automatic source code analysis:
results of the source code analysis are stored in a database table; repository table has a column where problems found in code are flagged,
tool checks for java imports that are not allowed, notifies about this and sets error flag in the database table,
tool also uses the Antrl parser generator to check if method implementations in the source code violate any rules and if the code does not do the things it should do.
Remote repo checks for both github and gitlab:
checks that remote is not public, the rule of the course,
checks that remote has only allowed contributors.
Testing and grading enhancements
tests are now grouped to grade level tests,
when all tests in a grade group passes, grade is stored to repository table,
grade tests can be executed in whichever order, since grade value is bit flag,
test for a certain student repository can be disabled if they cause issues like tests never ending or taking way too much time,
if git pull updates code, grade is set to zero and test results are cleared.
Status reporting
the tool now generates a textual status report that can be sent to student by email, listing how test pass, if any forbidden things are used / things to use are not used, git statistics etc.
Let’s take a closer look at the code analysis done by the tool in this post. The other features are left for future possible posts to discuss.
Analyzing if the source code uses “forbidden” imports was implemented with simple text parsing techniques. The tool goes through the Java source files in a certain directory where student code is located, reads the .java files and checks if the source uses imports that are not allowed.
For example, when implementing a Stack data structure, student must not import the java.util.Stack and just use it instead of implementing their own stack from scratch, using an array as internal data structure. Or when sorting an array, java.util.Arrays is not imported and Arrays.sort is not used, because student should have used their own implementation of the sorting algorithms.
These kinds of mistakes can be found by analyzing the imports in the student’s .java files. You cannot call Arrays.sort without having import java.util.Arrays in the .java file.
The tool first reads a rules file that contains the import rules for the course:
For example, the java.util.Comparator may be used by the students in all of their .java files (*). The same goes with java.util.function.Predicate and all the files in package oy.interact.tira (the course source packages). The class SetImplementation may also import java.util.Iterator.
Et cetera. As you can see, this is an allow list, not a deny list. The imports that are allowed and can be used in the course are small in number, so it is easier to have an allow list than deny list.
Reading the allow list and analyzing the source files was straightforward to implement by simple file handling and text parsing. First read in the rules file and parse the import rules from there, into this structure:
fileprivate
struct SourceRequirementsSpecification {
   var allowedImports: [String: [String]] = [:]
The Swift dictionary object allowedImports has the class as the key (either * or the name of the class rule is about), and then the array of allowed imports the class may contain.
Then the tool starts reading the student .java files and handles all lines beginning with import to check if that class may import that specific thing or not. If the .java file imports something that was not allowed, the tool database table (for the student’s repository) having a column with integer value, a specific bit in that number (a “flag”) is set to 1 (true). This indicates that the student’s code imported something it was supposed to not do.
This is the data structure keeping track of these repository flags, if they are set or not set:
struct Flags: OptionSet {
   typealias RawValue = Int16
   var rawValue: Int16

   static let remoteFails = Flags(rawValue: 1 << 0)
   static let buildFails = Flags(rawValue: 1 << 1)
   static let usesForbiddenFeatures = Flags(rawValue: 1 << 2)
   static let repositoryIsPublic = Flags(rawValue: 1 << 3)
   static let repositoryHasOutsideCollaborators = Flags(rawValue: 1 << 4)
   static let repositoryTestingIsOnHold = Flags(rawValue: 1 << 5)
}
The Swift OptionSet is a type that presents a mathematical set interface to a bit set. So each flag is a single bit in the 16 bit integer, being either off (0) or on (1). So instead of having six boolean columns in the database table, I can have one 16 bit integer column to store 16 different flags. Most of those still available for future needs.
The flag usesForbiddenFeatures is set in this case of student code using forbidden imports (or other features, discussed below). Other flags are used to:
track if the remote repository cannot be accessed at all (remoteFails) or is empty,
compiling the code fails (buildFails),
repository is public even though it must be private (repositoryIsPublic) and finally
if the repository has other collaborators than the student owning the repo and the course teachers (repositoryHasOutsideCollaborators).
These are all issues that have been met in the course during the previous years.
Final flag repositoryTestingIsOnHold can be set manually from the tool user interface for those repositories that mess up the testing, either because the tests are stuck or take too much time and therefore should not be executed before fixed.
That flag struct is a 16 bit integer, the datatype of the database column storing the flags in each student repository database table. If the code has issues related to these rules, the flag is set. When the git repository is updated from the remote, the user needs to run the code analysis again. If a violation of a rule was fixed, the flag is then reset to zero (false), if no other violations are found.
The imports checking from source code is not enough, though.
Sometimes students do mistakes in method implementations they are not supposed to do. Like when implementing a recursive binary search, they implement an iterative binary search. Or when sorting a table in descending order, they first sort in ascending order and then reverse the table order. Since time efficiency is the major topic of the course, this is not what they are supposed to do. Instead, they should use a comparator to sort the table to descending order in the first place, and then no reverse operation is needed at all, making the operation faster.
For checking these kinds of issues the import rules are not enough since these kind of mistakes can be made without importing something. Therefore, the same rules file contains also rules like this:
[codeRules]
# Algorithms.binarySearchRecursive must contain word binarySearchRecursive
Algorithms.binarySearchRecursive,must,binarySearchRecursive
# Algorithms.binarySearchRecursive must not contain word while
Algorithms.binarySearchRecursive,mustnot,while
Algorithms.binarySearchIterative,must,while
CodeWordsCounter.topCodeWords,must,Algorithms.fastSort
CodeWordsCounter.topCodeWords,mustnot,Algorithms.reverse
Here lines beginning with # are comments and ignored by the tool. Illustrating the examples of mistakes above, the rule:
Algorithms.binarySearchRecursive,mustnot,while
specifies that the algorithm binarySearchRecursive in class Algorithmsmust not contain the keyword while. Since breaking this rule implies that the student has implemented the recursive algorithm using iterative approach. Therefore, the learning goal of implementing a recursive binary search has not been met, and code needs to be fixed.
These rules are also parsed from the rules file into the above mentioned rules structure, which now looks like this:
enum Rule {
   case must
   case mustNot
}

struct CodeRule {
   let methodName: String
   let rule: Rule
   let stringToMatch: String
}

fileprivate
struct SourceRequirementsSpecification {
   var allowedImports: [String: [String]] = [:]
   var rules: [String: [CodeRule]] = [:] // ClassName : CodeRules
}
In addition to the allowedImports rules, the structure now contains also rules for a class (the Swift dictionary key String has the class name), where the CodeRule structure has the name of the method the rule is about, then if the method must or must not (Rule) contain the string to match.
This is a very simple current implementation, and as I develop this further, it may change to something different later. For example, it should be possible to say that the recursive binary search algorithm must not contain “while” but also not the “for” keyword.
The second example about being able to realize that descending order can be implemented by a specific comparator (instead of ascending sort and then doing reverse, which is more time-consuming operation) is checked by the rule that the class CodeWordsCounter in the algorithm topCodeWords (where the work in the coding task is done) must not call Algorithms.reverse.
If a student uses the Java Collections.reverse or Apache Commons ArrayUtils.reverse for this, that mistake is already caught using the import rules.
For this feature implementation, I used the Antrl parser generator. Antlr has existing grammars for many languages, including Java, and it supports generating parsers also for Swift. So all I needed to do was to get the Antlr tool and the Java grammar files (Java20Lexer.g4 and Java20Parser.g4) and then generate the Java parser and lexer for Swift:
$ antlr -Dlanguage=Swift -message-format gnu -o Autogen Java20Lexer.g4
$ antlr -Dlanguage=Swift -message-format gnu -o Autogen Java20Parser.g4
Those commands place the generated Swift source code files in a subdirectory named Autogen.
Using the generated Swift code from Autogen, the tool can then parse Java code. All I needed was to implement a class that extends the Antlr generated Java20ParserBaseListener, give the rules to this class and start parsing the source string read from the student’s java file, containing the Java source code:
import Antlr4
class Java20MethodBodyChecker: Java20ParserBaseListener {

   private let file: String
   private let rules: [CodeRule]
   private var currentMethod: String = ""
   private var stream: ANTLRInputStream? = nil

   var violations: [String] = []

   func start(source: String) throws {
      stream = ANTLRInputStream(source)
      if let stream {
         let lexer = Java20Lexer(stream)
         let parser = try Java20Parser(CommonTokenStream(lexer))
         let parserTree = try parser.compilationUnit()
         let walker = ParseTreeWalker()
         try walker.walk(self, parserTree)
      }
   }
// ...
Analysing the code happens in the overridden handler for parsing Java methods, enterMethodDeclaration. There, the implementation checks, using the rules, if the Java code contains any keywords that should not be there or does not contain keywords that should be here:
override func enterMethodDeclaration(_ ctx: Java20Parser.MethodDeclarationContext) {
 if let identifier = ctx.methodHeader()?.methodDeclarator()?.identifier() {
  currentMethod = identifier.getText()
  let ruleSet = rules.filter( { $0.methodName == currentMethod } )
  if !ruleSet.isEmpty {
   if let body = ctx.methodBody() {
    let bodyText = body.getText()
    for rule in ruleSet {
     switch rule.rule {
      case .must:
       if !bodyText.contains(rule.stringToMatch) {
        violations.append("\(file).\(rule.methodName) ei käytä \(rule.stringToMatch), vaikka pitäisi")
       }
      case .mustNot:
       if bodyText.contains(rule.stringToMatch) {
        violations.append("\(file).\(rule.methodName) käyttää \(rule.stringToMatch),  vaikka ei pitäisi")
       }
     }
    }
   }
  }
 }
}
The violations then contains all the things found to be against the rules.
This worked, except for one thing: if the code has comments that do/do not have the specified keywords of the rules, the code analysis did check those comments also. Even though the comments do not influence the implementation and are therefore totally irrelevant.
So if the comments of recursive binary search algorithm contains the keyword while, the tool would report that as a violation of the rule! Or if the code contains a required keyword, but not in the actual code implementation but only in the comments, the analysis would be satisfied. End result: not satisfactory at all.
First I started to fix this by implementing code myself to remove the comments from the code in a String variable before the analysis, but soon I realized that the Antlr parsing tool should somehow already handle this.
What I did instead, was (after some searching on the internet) to modify the Antrl lexer file for Java so that it does not parse the comments at all, but skips them:
Then I regenerated the Swift parser and lexer source files and added them to the tool project.
Using the new lexer/parsers, the parsed Java code does not anymore include comments and I do not have to consider them at all! This works perfectly.
Without asking anything about any “AI” tools out there. As usual, I do not touch them even with a long stick. I prefer to discover and learn myself, as long as the internet is not polluted with “AI” generated crap which makes everything impossible.
Below you can see the tool reporting about imports in a student repository, imports that should not be in the code, and that the code in CodeWordsCounter.topCodeWords does not call Algorithms.fastSort, even though it should, based on the rules in the rules file.
As you can see, the first violation is because the student has misnamed the class as setImplementation. In Java, classes (and therefore also class files) should always begin with capital letters and the name should be SetImplementation instead. So this is a mistake, but actually does not violate the import rule; the Set data structure implementation may use the Iterator. Therefore, when the rules are found to be violated, it often requires human rechecking to make sure no unfair judgments are made by the automation.
Considering the 300 something students in the course, perhaps each of them making at least 3-5 mistakes the code analysis could find, this results in 900-1500 mistakes in total. For the teacher to comb through all the hundreds of lines of code in each of the student projects, repeatedly during the course, working on this “code quality control” task manually is very time consuming and therefore not a realistic task. Especially considering the available teaching resources mentioned in the beginning.
Hopefully the new features of this tool and the similar tests given to students in Java test code, improve the support the teachers can provide during the course to lead the students to the correct path of implementing the required data structures and algorithms.
The post is getting quite long, so the rest of the new features will perhaps be discussed in future posts. Unless I decide to focus on other more interesting topics. Have a nice day!